MapReduce with OpenMP and MPI
ProjectCOpenMPMPI
May 1, 2022
On this page
This project implemented MapReduce across several multi-core machines. Its job was to index words from large input text files while distributing the workload across concurrent processes and nodes.
The goal
The implementation needed to process each word efficiently, merge independent concurrent processes, and keep time and space complexity in view.
The approach
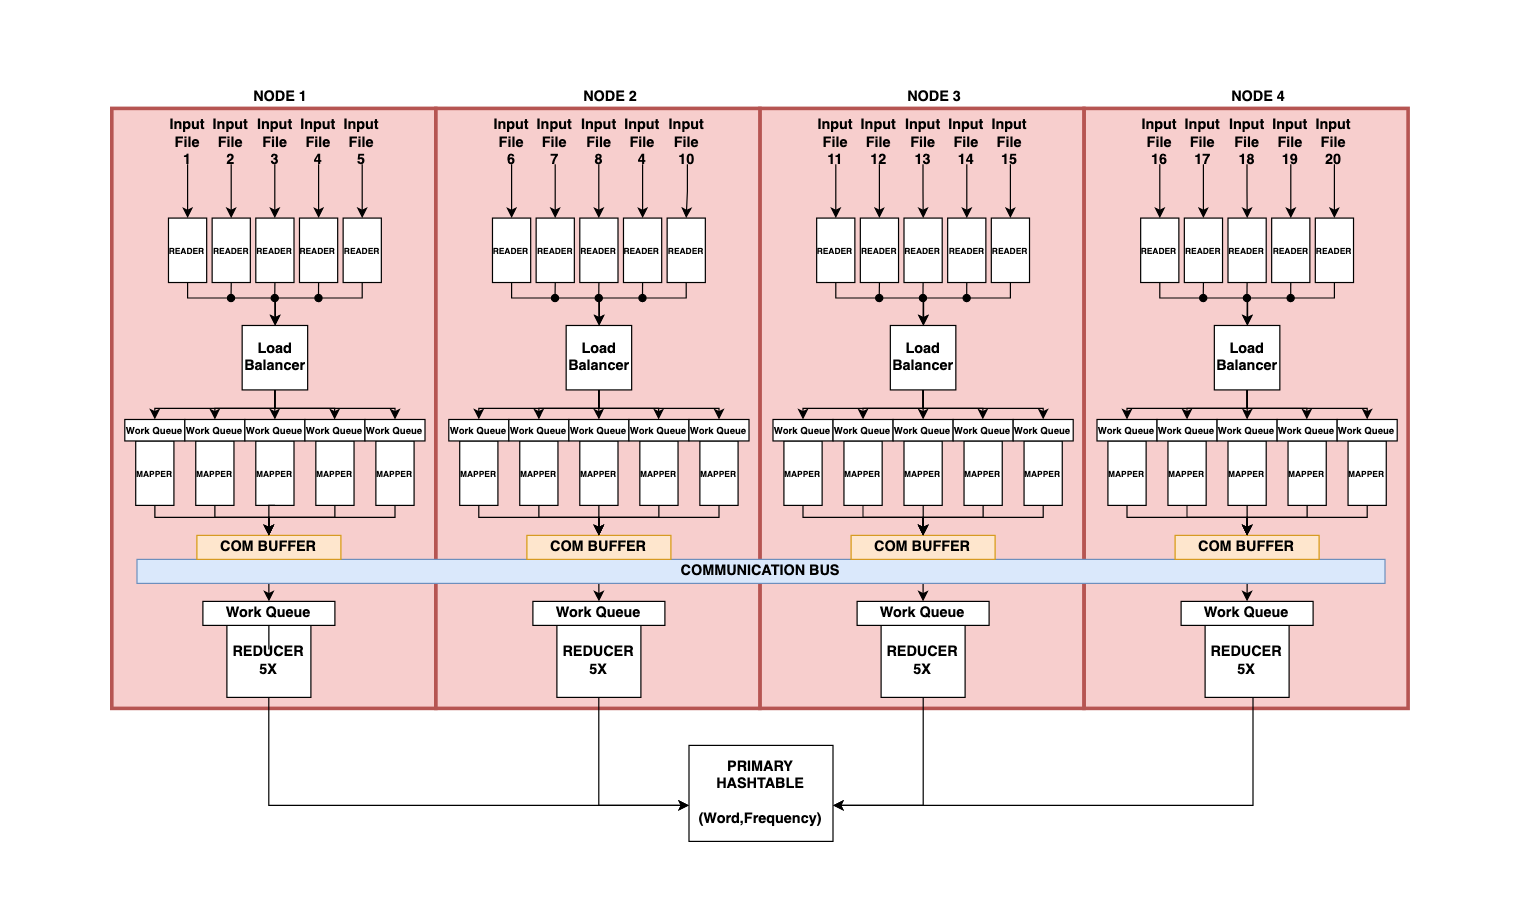
Input files are parsed to retrieve word counts across all input files. There are two main steps to process the input:
- Map step to parse input sets and sort into various groups.
- Reduce step to perform a summary operation.
Each process is responsible for either reading/parsing input files, mapping key/word pairs to respective reducer queues, and reducing word pair counts across processes.
The project implements this both locally on one node with OpenMP and in parallel across multiple machines with OpenMPI.
Performance analysis and isoefficiency analysis was detailed in the project report (PDF). We were able understand possible bottlenecks, efficiency of parallelism, and identify areas for future optimizations.